
Caching in system design: hit ratio, cache-aside and cache stampedes
A cache keeps copies of frequently read data in fast memory so most requests never reach the database. Done well it is the cheapest capacity you will ever add; done carelessly it hides a database that cannot survive without it.
Why caching works: the hit-ratio formula
Reads that hit the cache are answered in well under a millisecond. Only misses — plus every write — reach the database. The share of reads served from the cache is the hit ratio, H.
That gives the single most useful formula in caching. With a 90% hit ratio, the database sees one tenth of the reads it would otherwise see. Because writes always go through, write-heavy workloads benefit far less.
Database load = λ_read × (1 − H) + λ_write
Cache-aside, read-through and write-through
There are two common ways to wire a cache, and they differ in who talks to the database.
- Cache-aside (lazy loading): the application checks the cache; on a miss it reads the database and writes the value into the cache. The most common pattern with Redis or Memcached.
- Read-through: the application only talks to the cache, and the cache loads misses from the database itself. Simpler application code; used by DynamoDB Accelerator (DAX) and caching layers.
- Write-through: writes go through the cache to the database, keeping the cache populated. Write-around and write-behind are variations with different durability trade-offs.
Invalidation and TTLs
A cached value is a copy, and copies go stale. Most systems delete the cached key whenever the underlying row changes (invalidation) and also give every key a time-to-live so mistakes heal themselves.
Both reduce the hit ratio: every invalidation and every expiry creates a future miss. A write-heavy workload with short TTLs can have a much lower hit ratio than its access pattern suggests — this is why a cache rarely reaches its theoretical maximum.
How much memory a cache needs
A cache helps only with keys it currently holds. The working set is the set of keys your traffic actually uses in a period. If memory is smaller than the working set, keys are evicted before they are reused.
Redis’s allkeys-lru evicts the least recently used keys; noeviction refuses new writes with “OOM command not allowed”. Neither is a substitute for sizing the cache for its working set.
Memory needed ≈ working-set keys × average item size
Cache stampedes and cold starts
The most dangerous moment for a cached system is when the cache is empty: after a deploy, a restart, a flush or a mass expiry. Every read becomes a miss and the database suddenly receives several times its normal load.
If the database was sized for the cached load, it falls over — and while it is slow, the cache cannot warm up. Defences include warming caches before sending traffic, request coalescing (one database read per missing key), staggered TTLs, and sizing the database to survive a cold cache for a short time.
Caching beyond the application: CDNs
A CDN such as CloudFront, Cloudflare or Fastly is a cache in front of your whole application, at edge locations close to users. The same formula applies: with a 95% edge hit ratio, only 5% of cacheable requests reach your origin servers.
Try it in the simulator
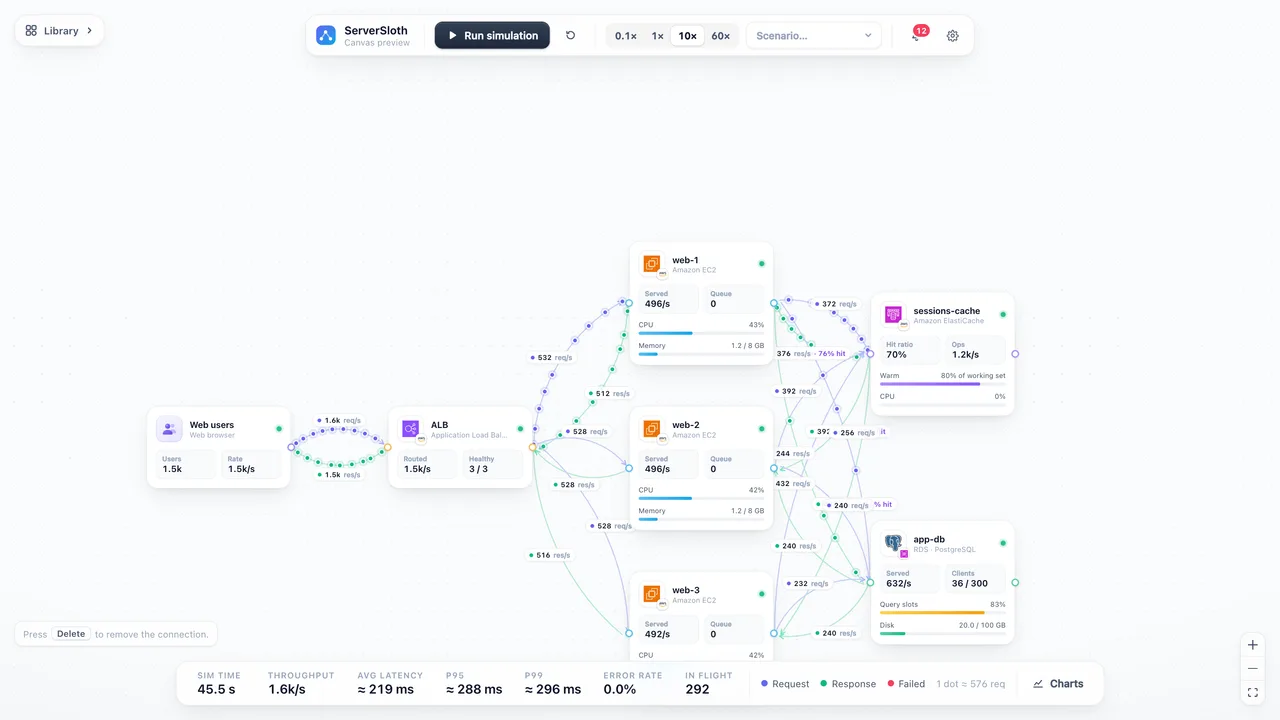 Startup
Cached web app
ALB → three EC2 servers using ElastiCache (cache-aside) in front of RDS PostgreSQL. At 60 s Redis is flushed.
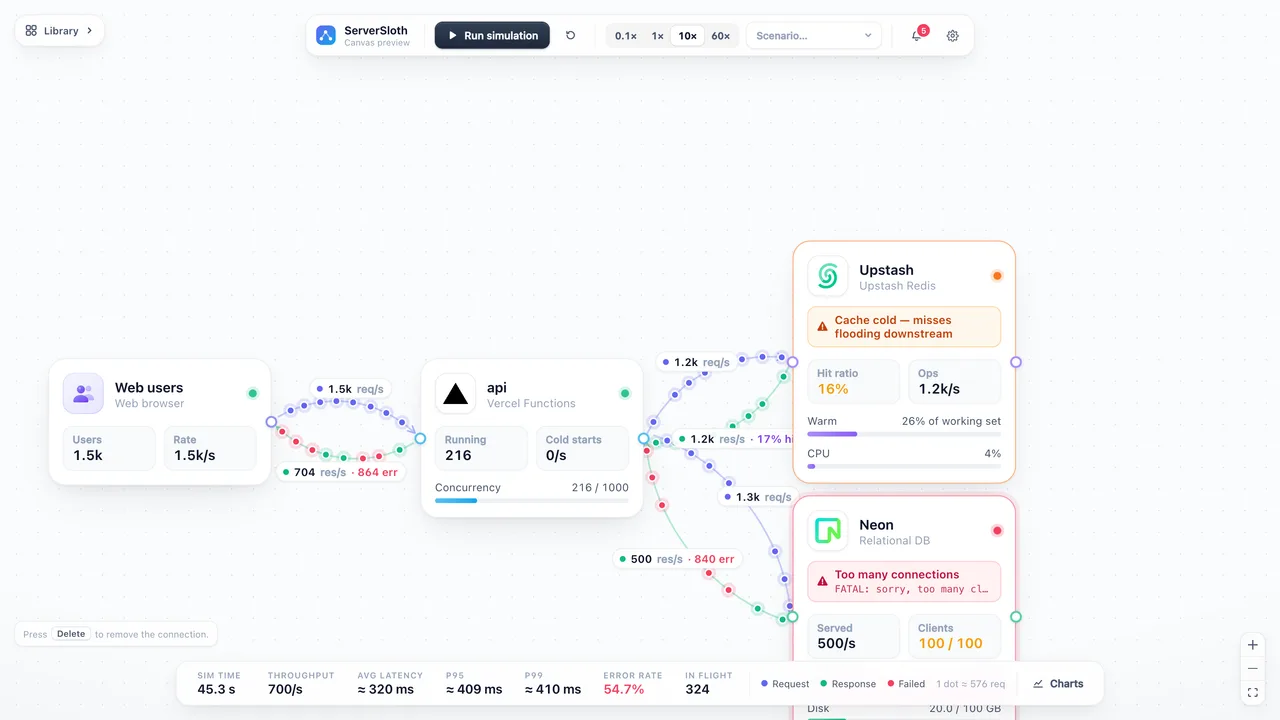 Startup
Serverless edge
Vercel functions → Neon Postgres, with Upstash Redis as a cache. Every function invocation can open a database connection.
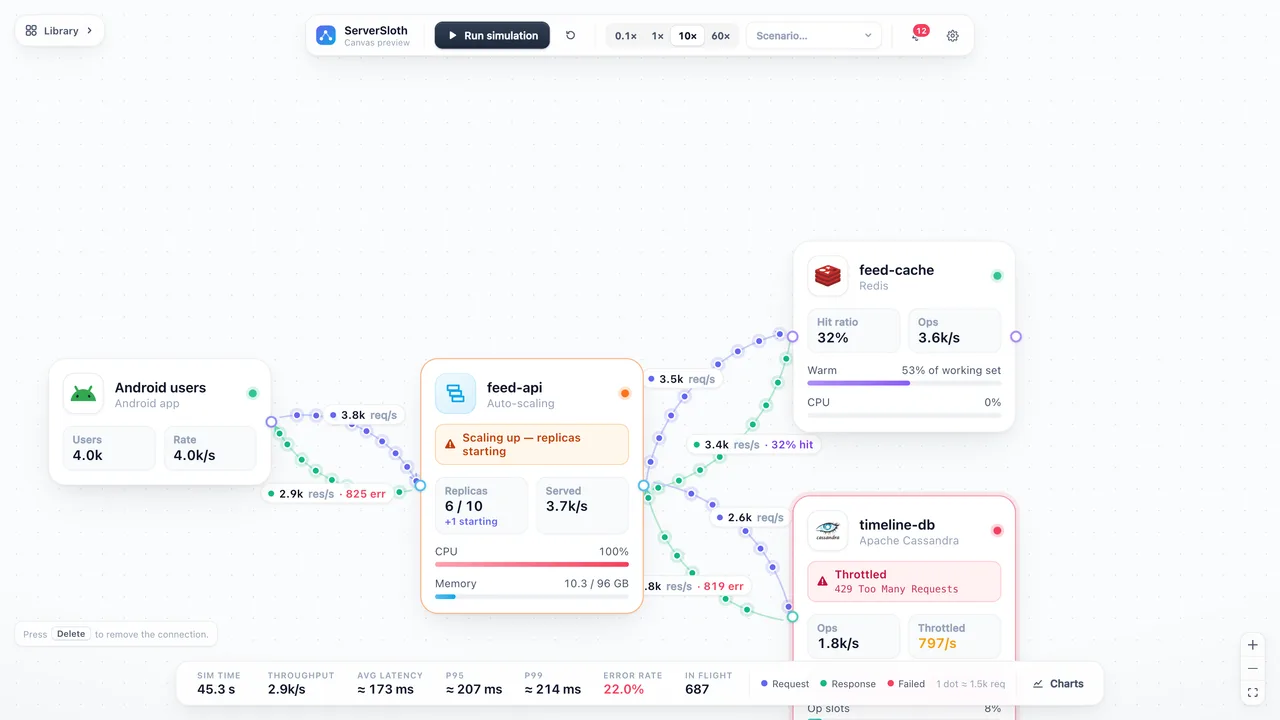 Global
Feed / timeline
API servers → Redis → Cassandra. A celebrity post makes one key take 60% of the traffic.