
Out of memory (OOM): why servers crash under load
A server crashes with “out of memory” when the requests it is holding need more RAM than the machine has. Under load this is rarely a leak: it is a queue that never stops growing.
What causes it
Every request a server is working on — or waiting to work on — holds memory: buffers, parsed payloads, ORM objects, a thread stack. When requests arrive faster than the server can finish them (utilisation ρ ≥ 1), the waiting line grows without limit, and so does the memory it holds. Slow downstream calls make it worse: a request waiting 2 seconds for the database holds its memory for 2 seconds.
How to recognise it
- Memory climbs steadily while CPU sits at 100%
- Latency rises sharply just before the crash
- Logs end with “Killed”, exit code 137 or OOMKilled in Kubernetes
The math
Memory ≈ base + memory per request × (requests in service + queued + waiting on downstream)
Error messages you will see
| Error | Seen in |
|---|---|
Killed by the Linux OOM killer | Users, Router, Server, Database, Cache, Queue and 197 more |
OOMKilled (exit code 137) | Kubernetes, Amazon EKS, Amazon ECS, AWS Fargate, Google Kubernetes Engine, Azure Kubernetes Service and 1 more |
OOM command not allowed when used memory > maxmemory | Redis, Valkey, Amazon ElastiCache, Amazon MemoryDB, Memorystore, Azure Cache for Redis and 2 more |
java.lang.OutOfMemoryError: Java heap space | Elasticsearch, OpenSearch, Amazon OpenSearch Service |
How to fix it
- Add another instance behind a load balancer
- Lower “Max queued” so excess load is rejected instead of crashing
- Increase RAM or CPU cores
- Make downstream calls faster (cache, more DB capacity)
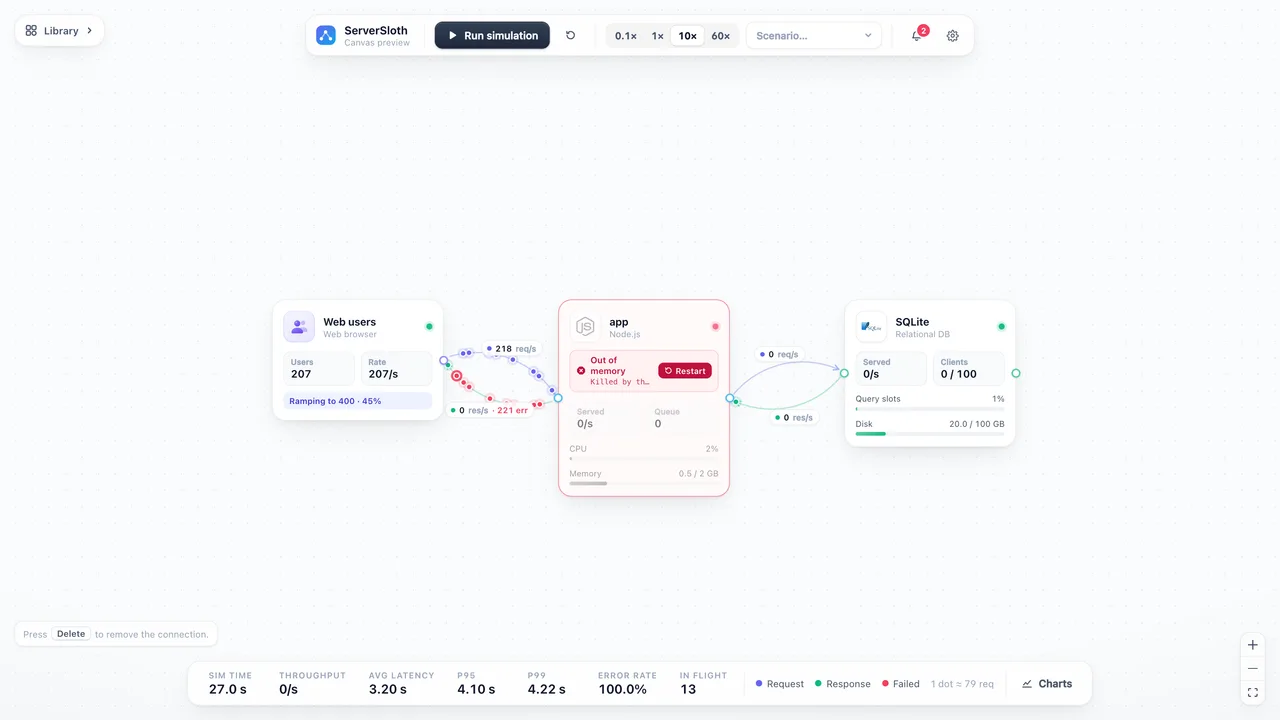
Reproduce it in the simulator
These templates trigger this failure on purpose:
Learn more
Part of the guide Load balancing and capacity planning.